Last week I released Paradee-8M-v1.1, a faster and clearer version of my small voice model distilled from Kokoro-82M. Until now Paradee only had one voice, Kokoro’s af_heart. Today I’m releasing Paradee-8M-v1.2, which has four voices in the same 8.5 MB file and without any quality loss.
Here’s one sentence read by each voice.
In the wild, parakeets fly in loud, colorful flocks across the open grasslands of Australia.
UTMOS (higher is better)
UTMOS is a model trained on human ratings that predicts how natural a clip sounds, on a scale from 1 to 5.
| UTMOS | Paradee-8M-v1.2 | Kokoro-82M |
|---|---|---|
| af_heart | 4.40 | 4.52 |
| bf_isabella | 4.06 | 4.41 |
| am_puck | 4.32 | 4.47 |
| bm_fable | 4.18 | 4.32 |
WER (lower is better)
WER is the share of words that Whisper, a speech recognition model, transcribes wrongly.
| WER | Paradee-8M-v1.2 | Kokoro-82M |
|---|---|---|
| af_heart | 5.8% | 5.7% |
| bf_isabella | 5.7% | 5.6% |
| am_puck | 5.4% | 6.3% |
| bm_fable | 5.7% | 5.7% |
These are measured on the same 200 held-out sentences as before. UTMOS predicts how natural a clip sounds, out of 5, and WER is the share of words Whisper mishears. af_heart scores 4.40, against 4.39 in v1.1, so adding the other voices didn’t reduce the existing voice’s quality. The file size and speed are the same as v1.1.
What changed
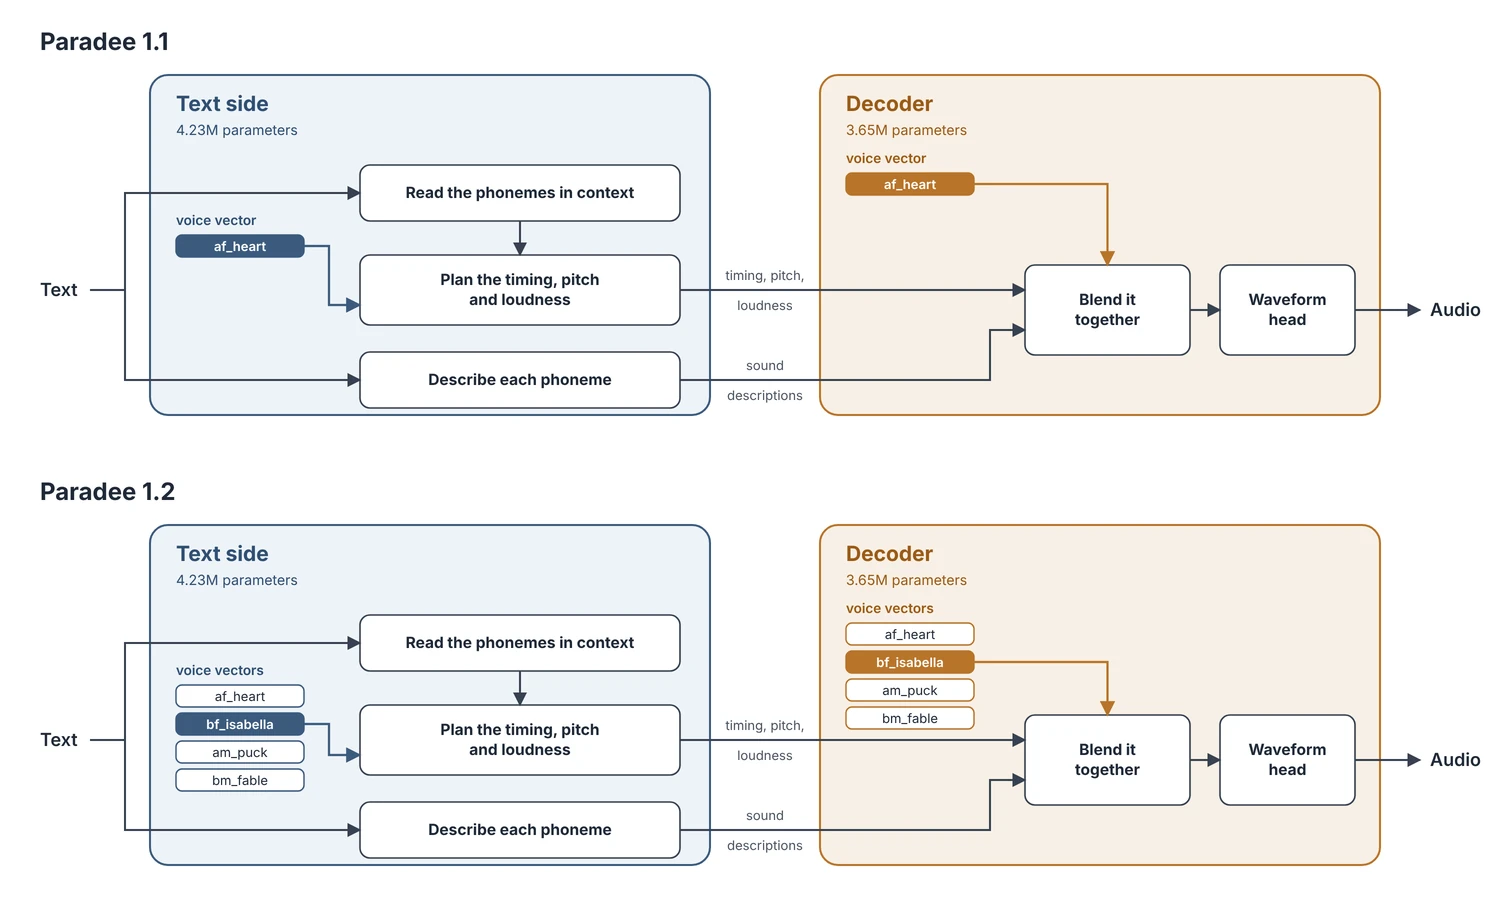
Kokoro describes each voice with a vector, and the model reads that vector at every step. Paradee 1.1 only ever saw one voice, so it learned a single fixed vector. For v1.2 each half of the model has a small table with one vector per voice, and the voice you pick chooses the row. Everything else is shared between the four voices.
The British voices also need British pronunciation. Kokoro uses different phonemes for the same word between British and American voices. Some examples of words with different American and British phonemes are included below:
| Word | American | British |
|---|---|---|
| avocado | ˌɑvəkˈɑdO | ˌavəkˈɑːdQ |
| tomato | təmˈATO | təmˈɑːtQ |
| schedule | skˈɛʤˌul | ʃˈɛdjuːl |
The phonemizer in the package and in Chickadee was updated to use British phonemes when a British voice is used.
In order to add the additional voices, I started from the v1.1 weights and kept training both the text-side and the decoder on Kokoro reading 12,000 sentences in each of the four voices. For more information on how the training of Paradee works, see Paradee: Distilling Kokoro-82M into an 8M-Parameter Single-Voice Text-to-Speech Model. The result is Paradee-8M-v1.2 with four voices, the same tiny model size, and no quality loss compared to v1.1 on its existing voice.
Try it
Paradee-8M-v1.2 is now the light voice in Chickadee, a Chrome extension that reads web pages aloud using local voice models. Choose Paradee as the model and pick one of the four voices.
The Python package uses v1.2 by default, and v1.1 is still available.
pip install git+https://github.com/sahilmahendrakar/paradee
python -m paradee "Paradee is a small voice that runs anywhere." --voice bf_isabella -o hello.wav
Links
- Model: Hugging Face
- Code: GitHub
- Chickadee: Chrome Web Store
- v1.0 Paper: Paradee: Distilling Kokoro-82M into an 8M-Parameter Single-Voice Text-to-Speech Model
- Earlier posts: Paradee 1.1, Paradee